
The computer science graduate co-authored research on adapting SAM2 through selective fine-tuning and compact visual memory, addressing the computing demands of analyzing longer videos.
SACRAMENTO, California – Qi Hu, an independent AI researcher and computer science graduate of Northeastern University, is a co-author of a study published in IEEE Signal Processing Letters that examines how a foundation visual AI model can be adapted to process long video sequences more efficiently.
The paper, “MFT: Memory-Aware Fine-Tuning of SAM2 for Efficient Long-Sequence Video Object Segmentation,” focuses on the cost of adapting a large segmentation model and managing information from earlier video frames. Hu is one of six authors, alongside Guoqiang Li, Hao Yuan, Suyang Chen, Jun Wang, and Kunming Jiang.
Following an Object Beyond a Single Frame
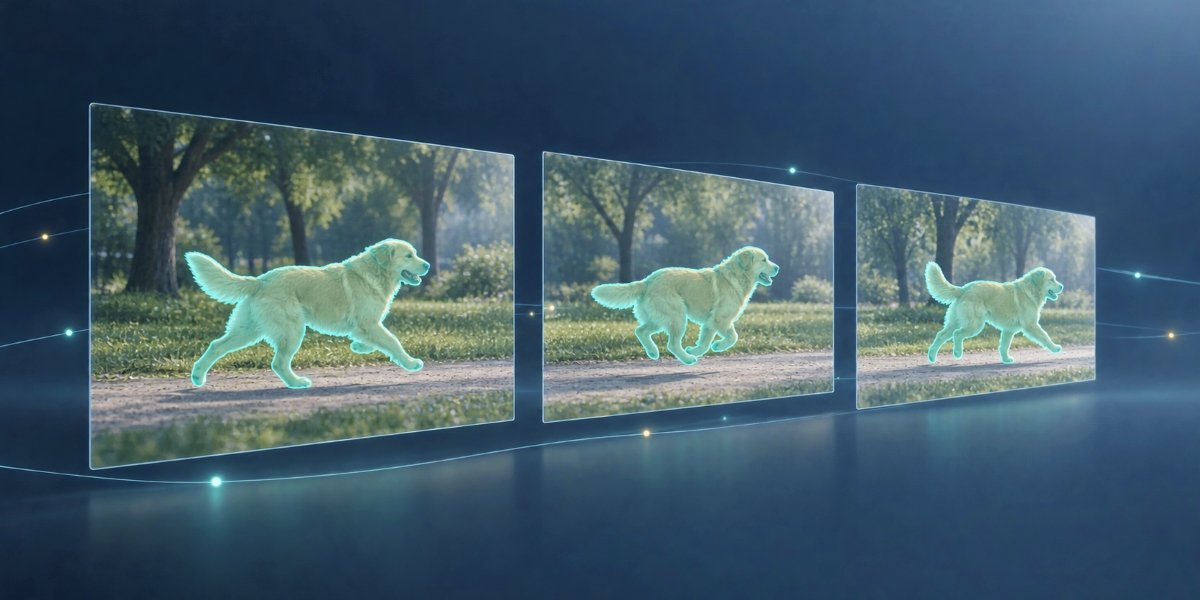
Video object segmentation asks an AI system to identify the pixels belonging to a particular object as it moves through a recording. Unlike a bounding box, which surrounds an object with a rectangle, a segmentation mask follows its visible outline. Maintaining that outline across a sequence requires the system to connect what it sees now with what it saw earlier.
SAM 2, or Segment Anything Model 2, provides a foundation for this task. It combines visual processing with a memory mechanism that carries information between frames. The MFT study examines how to adapt that foundation for long-sequence video object segmentation without relying on full-model fine-tuning.
A More Targeted Approach to Adaptation
Full fine-tuning updates the parameters throughout a model. MFT takes a more selective approach: it keeps SAM2’s image encoder fixed and trains selected components associated with memory processing and mask prediction, including memory attention, the mask decoder, and the memory encoder.
This distinction matters because adapting an existing foundation model is a separate engineering challenge from building one. A team may be able to access a pretrained model but still face substantial demands when tailoring it to a particular video task. MFT addresses that adaptation stage by narrowing which parts of the model are updated.
The study also introduces a lightweight Memory Compression network. Rather than allowing stored short-term representations to accumulate without a bound, the network periodically condenses them into a compact long-term representation. The purpose is to retain historical context while controlling the size of the memory bank.
Two Different Meanings of Memory
The research brings together two related but distinct ideas. In video AI, memory can mean the visual information retained from earlier frames. In computing, memory also means the hardware capacity required to store data during training or processing. Keeping useful context and limiting resource demands are not the same task, even though the two can affect one another.
MFT combines selective model adaptation with compressed historical representations to address this practical tension. The paper reports evaluations on long-sequence benchmarks and presents the approach as a resource-conscious way to adapt SAM2. Those findings concern the experimental settings studied; they should not be read as a guarantee of identical results on every device or video task.
A Research Question With Practical Stakes
For developers evaluating video AI, a useful question is not simply whether a model can segment an object, but what it takes to adapt the model and preserve relevant context over time. That makes training requirements and memory management important considerations alongside segmentation quality.
The MFT publication treats efficiency as part of the model adaptation problem rather than as an afterthought. Selective training addresses which components need to change, while memory compression addresses how earlier visual information is retained. Together, these design choices frame the study’s approach to extended video sequences.
For Hu, the publication forms part of a research record in artificial intelligence and computer vision. Its focus is a specific technical problem: how to adapt a foundation segmentation model for extended sequences while being more deliberate about the components trained and the information retained.
Publication Details
The study was published in IEEE Signal Processing Letters, volume 33, pages 943–947, in 2026. The paper is available through IEEE Xplore under document number 11386858, DOI: 10.1109/LSP.2026.3663047.
About Qi Hu
Qi Hu is an independent AI researcher and a computer science graduate of Northeastern University. Hu’s research interests include computer vision and AI methods for financial applications.
Media Contact
Audrey Smith
Email: audrey@jwoverseas.cn
Sacramento, California, USA


